News
Meta Names Dhruv Vohra to Lead Southeast Asia Business
Today we’re announcing that Dhruv Vohra is stepping into the role of Managing Director, Global Business Group, Southeast Asia.
Every story published that day — lead first, then grouped by section.
Today we’re announcing that Dhruv Vohra is stepping into the role of Managing Director, Global Business Group, Southeast Asia.
Today we’re announcing that Dhruv Vohra is stepping into the role of Managing Director, Global Business Group, Southeast Asia.
Deploying an HSTU Generative Recommender with NVIDIA Dynamo-Triton | NVIDIA Technical Blog Deploying an HSTU Generative Recommender with NVIDIA Dynamo-Triton By Junyi Qiu , Shijie Liu , J Wyman and Mudit Aggarwal Generative recommender systems reformulate personalization as sequence modeling over user behavior, and NVIDIA recsys-examples now provides an end-to-end HSTU inference workflow with Dynamo-Triton.
On Tuesday, executives for Google , Anthropic , Meta , OpenAI , xAI , and Nvidia all signed “The White House Accord on Super Intelligence,” which was announced following a luncheon held by President Donald Trump.
At a Make America Healthy Again event Tuesday, anti-vaccine Health Secretary Robert F.
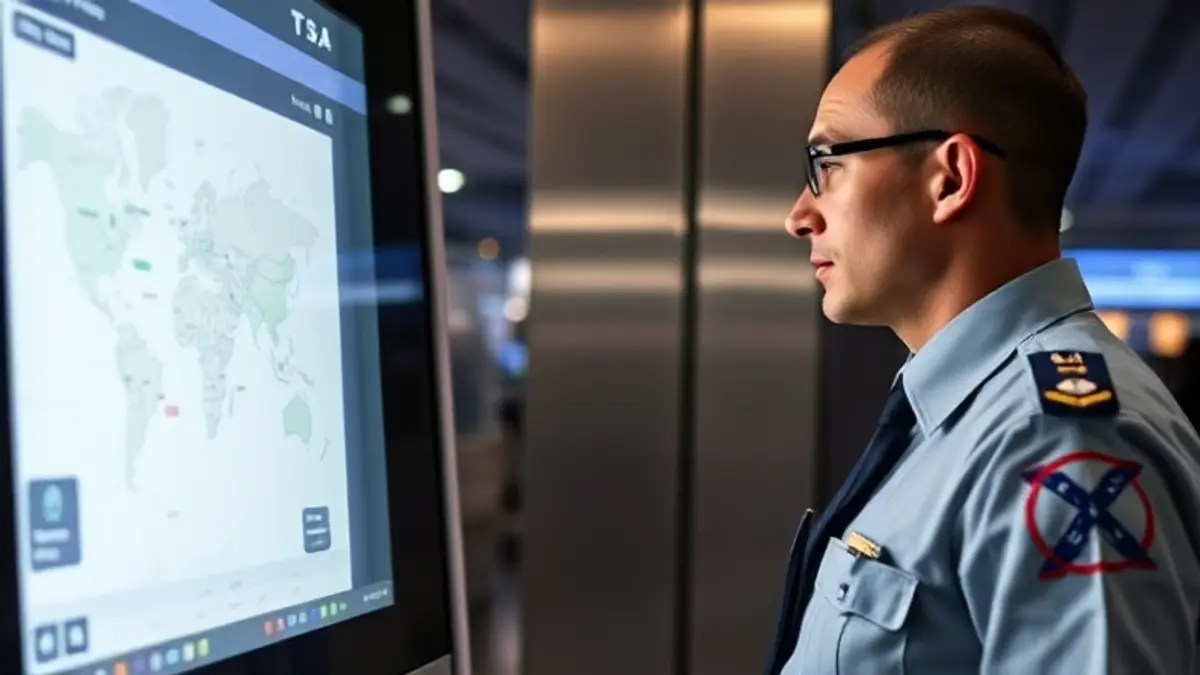
Salesforce has revealed Ace, a new AI agent for the TSA Ace should take the pressure of answering basic questions off human agents Ace has already resolved 96% of basic inquiries so far Salesforce has built the Transportation Security Administration (TSA) a new AI agent to try and help streamline travel for passengers everywhere.
Tracing Agent Harness Behavior with NVIDIA NeMo Relay | NVIDIA Technical Blog Tracing Agent Harness Behavior with NVIDIA NeMo Relay Learn how to use execution traces to understand agent behavior and determine whether harness changes improve task outcomes.
AI OpenAI connects the dots on always-on agents PLUS: Get started with ChatGPT dot, OpenAI's new agent Good morning, AI enthusiasts, and welcome to the 5,480 new readers who joined us yesterday. The always-on AI agent category has gotten pretty crowded this summer.
Runway app for iPhone Runway app for Android An open-weight world action model that turns Runway's video pretraining into control for real robots. “Pick up the tennis ball and put it in the box.” Today we're announcing Praxis-1 , our first open-weight world action model.
Google promised Gemini 3.5 Pro in June, but it spent the summer trotting out smaller Flash models.
Gemini 4 Argon: our next era of frontier intelligence Gemini 4 Argon delivers frontier performance in complex workflows across real-world software engineering, enterprise knowledge work like legal and finance, and cybersecurity defense. SVP, Google DeepMind and Chief AI Architect, Google Google’s new Gemini 4 Argon model brings advanced reasoning to complex, long-horizon professional tasks.
Expanding AI Storage Access with NVIDIA cuObject and the NVIDIA SCADA Server SDK | NVIDIA Technical Blog Expanding AI Storage Access with NVIDIA cuObject and the NVIDIA SCADA Server SDK By Harish Arora , Vikram Sharma Mailthody , Kiran K.
We present a robot exposure index based on how well robots can perform job tasks today. Robots, which we define as autonomous physical machines that sense and act, can perform three-quarters of physical tasks in the US, making up 34% of working hours, but mostly in limited settings.
At a glance End-to-end forecasting: A machine learning pipeline uses forecast-time solar-wind information to generate location-specific risk estimates for…
Building on nearly a decade of co-engineering, CoreWeave has built NVIDIA compute, networking and software into a cloud purpose-built for AI that’s still…
How well does nDCG capture the quality of modern retrieval systems? nDCG is the established yardstick for measuring how well search systems rank results, and is widely used across benchmarks such as MTEB and BEIR .
State-of-the-art enterprise retrieval: Embed 5 Pro achieves the highest average score of any model we tested, particularly across financial datasets, parsed PDFs, and visually rich documents. A new Fast tier: Embed 5 Fast brings strong retrieval quality to latency, and cost-sensitive workloads, at $0.08 per million tokens.
Top NewsAnthropic and OpenAI race to release smarter and cheaper modelsSources:Anthropic launches Claude Opus 5.5 with stricter safeguards for…
🎧 Audio version (or download audio for later): Good Morning, Dermot McGrath is an Irish entrepreneur and advisor based in Shanghai with over a decade…
On the Effectiveness-Fluency Trade-Off in LLM Conditioning: A Systematic Study - Apple Machine Learning Research research area Methods and Algorithms , research area Speech and Natural Language Processing conference EMNLP content type paper published September 2026 On the Effectiveness-Fluency Trade-Off in LLM Conditioning: A Systematic Study Authors Iuri Macocco†, Pau Rodríguez Lopez, Arno Blaas, Luca Zappella, Marco Baroni†*, Xavier Suau...
SCLATE: A Substrate for Continual-Learning Agent Training and Evaluation - Apple Machine Learning Research research area Methods and Algorithms , research area Tools, Platforms, Frameworks content type paper published September 2026 SCLATE: A Substrate for Continual-Learning Agent Training and Evaluation Authors Youngmok Jung, Sirajul Salekin, Henry Tran, Javier Movellan, Zhao Huang, Manjot Bilkhu Continual-learning agents are systems of models, harnesses,...
Three months ago Dwarkesh, who has been posting incredible blogs and episodes about RL, posted a framing question for his video essay on RLVR which upset a…
Fetch the complete documentation index at: /llms.txt Use this file to discover all available pages before exploring further. The Decisions API is billed at $0.04 per million input tokens.
ai_decide is a new Databricks AI Function that makes fast decisions directly on your data. It takes unstructured text and returns structured decisions in a fraction of a second.
We recently closed a $300 million employee tender offer that values ElevenLabs at $22 billion, double our valuation at our Series D in February. The round was led by Wellington and T.
Modulate , the Boston audio AI company behind a gaming voice moderation tool called ToxMod , has raised USD $25 million in new funding.
Does a real video show an airplane spinning wildly on a runway and hitting several other vehicles? No, that's not true: The video appeared on TikTok labeled as AI-generated content.
Today is the 20 year anniversary of Sam Altman’s first startup, and fittingly OpenAI the consumer AI company is so back (as is OpenAI the AI Cloud and…
Bringing together the world’s brightest minds and the latest accelerated computing technology leads to powerful breakthroughs that help tackle some of the…
Lakebase is cost-efficient by design because its separated storage and compute architecture lets branching, read replicas, and high availability share one storage layer, while serverless autoscaling and scale-to-zero mean you pay only for the compute you actually use.
As agentic applications become more autonomous, enterprises need shared infrastructure for context, model, and tool access; governance; evaluation; and observability, rather than rebuilding these capabilities for every agent.
Google.org announced on Sept. 15 that the MIT Transit Lab is a recipient of $2.1 million in funding — one of only 15 projects selected in the worldwide…
A new AI system that excels at challenging games with hidden information could someday help human decision-makers select ideal strategies to outfox opponents…
Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning Open TTS Leaderboard: Scalable Evaluation for Multilingual Text-to-Speech and Voice Cloning TLDR 👉 new TTS leaderboard focused on open-source and multilingual The pace of open-source text-to-speech (TTS) model releases has been incredible.
Amid escalating AI security incidents causing OpenAI to halt training and pause releases, Donald Trump continues to advocate for the AI industry to regulate…
OpenAI's hack of Hugging Face in July 2026 has spurred a lawsuit demanding that the company stop accessing third-party computer systems and halt AI…